Saturday, 28 May 2011

Lie Markov Models

Jeremy Sumner, Jesus Fernandez-Sanchez and Peter Jarvis have a paper recently made available at thehttp://www.blogger.com/img/blank.gif Arxiv. The paper is theoretical in nature but gives an interesting application of group theory to Markov models.

The practical problem addressed is determining the conditions under which a non homogeneous continuous time Markov model can be represented by a "time averaged" homogeneous Markov model, i.e. what constraints are required to ensure a rate matrix exists such that

for rate matrices . This has application for phylogenetic methods, where typically a single rate matrix is fitted to an evolutionary history. However, rates may in fact change over time. The question is then under what conditions could the single rate still be in some sense valid in summarising the time averaged process.

The authors show that the model for Q must be a Lie algebra. They also give the possible model forms for three and four state models under symmetry constraints. Update: This paper has now been published in the Journal of Theoretical Biology.

Tuesday, 10 May 2011

A proportional hazards regression model for the subdistribution with right-censored and left-truncated competing risks data

Xu Zhang, Mei-Jie Zhang and Jason Fine have a new paper in Statistics in Medicine. This covers the same ground as the paper by Geskus in Biometrics, in developing an approach to fitting the Fine-Gray proportional subdistribution hazard model for competing risks data with left truncated and right censored observations by using inverse probability weights (IPW). Bizarrely, the paper makes no reference at all to the Geskus paper. Presumably this is because the paper was first submitted in 2009 before Geskus's work was published (April 2010). However, it is strange that neither the authors nor the referees became aware of the work in the interim (i.e. acceptance of the paper wasn't until March 2011).

What is interesting is the differences between the approach taken in this paper compared to Geskus. The authors work on the basis that since X = min(T,C) is only observable if X > L, where T is the time of failure, L the time of left truncation and C the time of right censoring, the IPW should be calculated conditional on L < X. Zhang et al use a stabilised weight rather than the IPW to reduce the variability in the original weight. The weights they derive seem quite different to Geskus's as they depend on an estimate of overall survival, which will have to depend on the covariates if the semi-parametric model for the subdistribution hazard is to apply.
The authors suggest using Aalen additive hazard models for the overall survival (thus allowing for time varying covariate effects that can ensure the weights are consistent with the proportional subdistribution hazard model).

Zhang et al start from the general case where the truncation and censoring distributions depend on covariates (but are independent conditional on these covariates), though they only detail non-parametric estimates of the weights. Geskus argued that even if the censoring/truncation distribution depended on covariates that didn't imply it was necessary to include these covariates in the weightings.

Given these discrepancies it would be of interest to contrast and compare the two approaches to the same problem. If both approaches are effective, Geskus's seems preferable because the weights are much easier to calculate.

Wednesday, 4 May 2011

Discrete-time semi-Markov modeling of human papillomavirus persistence

Mitchell, Hudgens, King, Cu-Uvin, Lo, Rompalo, Sobel and Smith have a new paper in Statistics in Medicine. This considers a non-parametric estimator for a 2-state discrete-time semi-Markov process. Following Kang and Lagakos who assume one of the two states (e.g. state 0) is Markov, the process can be characterised by
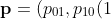
where is the probability of making a transition from 1 to 0 given i time units spent in state 1,
is the maximum length of state sequence observable in the data and
Extensions to the model, allowing to depend on time in state and to allow an additional disease-free state corresponding to disease-free with no past disease, are also proposed. Missing observations can be dealt with by summing over all possible observed states at the missing times. Estimation of is by maximum likelihood. An acknowledged limitation is the inability to cope with the case of unknown initiation times if either the sojourn distribution of state 0 is non-geometric or observation can start in the disease state.

Of particular interest to the authors is an estimate of 'persistence' of the disease state. This is defined as spending j time units in the disease state, counting single disease free (negative) observations surrounded by positive observations as time spent in the disease. The probability of persistence is just a function of the transition probabilities and so readily estimable.

The authors claim that their discrete time model doesn't not require a "guarantee time" unlike Kang and Lagakos. This is obviously ridiculous, the discrete time model requires a guarantee time of 1 time unit for all transitions! While adopting a discrete time model simplifies the problem of inference to something quite trivial, one has to question how realistic it is to model something that is clearly a continuous time process as discrete time. Bachetti et al's more general approach is along similar lines. Similarly, while the estimation is nominally non-parametric, the discrete time assumption is in many respects more severe than, say, constraining sojourn distributions to be Weibull distributed.

The clinical definition of persistence which makes the assumption that a negative observation between two positive observations counts as a positive is easily accommodated for via the discrete time model. However, a more satisfactory approach would be to adopt a more formal definition, based in continuous time, e.g. persistence if disease free period is less than say 6 months. This would have parallels with the approach taken by Mandel (2010) in defining a hitting time in terms of having a sojourn of more than some length in the disease state. Farewell and Su also dealt with a similar problem but their approach seems to be best avoided.

Thursday, 28 April 2011

Bayesian evidence synthesis for a transmission dynamic model for HIV among men who have sex with men

Presanis, De Angelis, Goubar, Gill and Ades have a new paper in Biostatistics. The paper attempts to use several disparate sources of data on prevalence and incidence to estimate transition rates and prevalences in a multi-state model of transmission of HIV among men who have sex with men (ironically abbreviated as MSM) via Bayesian evidence synthesis. The multi-state model has 4 transient states relating to "Eligible (non MSM)", "Susceptible (MSM)", "Undiagnosed" and "Diagnosed". Subjects enter aged 15 (or later due to migration) and may exit due to death or reaching age 45.

It should be noted that the multi-state model is deterministic and not stochastic, i.e. the proportions in each state at a given time conditional on the parameters and starting conditions are the solution of an ordinary differential equation. While this is unproblematic in terms of getting estimates of the expected proportions in each state at a given time, there must be some level of under representation of the uncertainty. In particular the likelihood assumes that the number of deaths from HIV from the SOPHID dataset at time is where is the number in the diagnosed state at time and is the probability of death in one year from HIV for the year . In reality D(t) should be stochastic rather than deterministic and as such we would expect the number of deaths to have a higher variance than assumed by the binomial model.

In principle the covariance matrix of the numbers in each state for each year could be derived, i.e. given the Markov model, we have N independent individuals each of whom's state occupancy at time is multinomial given the occupancy at time . A more realistic model would then assume that conditional on the parameters, the state occupation counts have a multivariate normal distribution (e.g. analogous to the approaches taken in the estimation of aggregate Markov data) and, for instance, the number of deaths from HIV is binomial with a denominator that is itself normally distributed. Quite possibly this extra source of uncertainty is negligible compared to the vast existing uncertainties but it nevertheless ought to be explored.

Friday, 15 April 2011

On inference from Markov chain macro-data using transforms

Martin Crowder and David Stephens have a new paper in Journal of Statistical Planning and Inference. This considers estimation of a discrete-time homogeneous Markov chain from aggregate data (which they term macro-data), ie. where only the overall state counts for N patients are known at time j, while the transition counts are unknown. The likelihood for such data is intractable because it involves summing over the vast number of possible transitions that are consistent with the observed aggregate counts. As a result, inference methods have focused on moment based estimation (see e.g. Kalbfleisch, Lawless and Vollmer, Biometrics 1983) which are reasonably effective in practice.

Crowder and Stephens note that the probability generating function for the observed aggregate counts has a fairly simple form. This motivates an estimation procedure based on trying to match the quantities with their expectations (i.e. the pgfs). An obvious practical issue is the choice of vectors to use to compare the closeness between the pgf and sample quantities. The authors propose choices that avoid computational problems for large sample sizes.

Through a series of simulations, the authors demonstrate that an improvement in efficiency compared to methods based on second moments is possible for small sample sizes (e.g. n <= 25). A comparison is made with the efficiency for micro-data (i.e. where transition counts are known). However, for such small samples computation of the full likelihood for the aggregate data must become a viable option. The practical issues are whether the pgf based approach gives any real improvement in efficiency compared to second moment approaches for say n=100 (the second moment approaches are asymptotically efficient with appropriate weights) or whether the pgf method outperforms (or matches) the full likelihood for small samples sizes (i.e. n<=25) where the full likelihood is calculable. These issues aren't really addressed in the paper.

Thursday, 14 April 2011

Non-homogeneous Markov process models with informative observations with an application to Alzheimer's disease

Baojiang Chen and Xiao-Hua Zhou have a new paper in Biometrical Journal. The methodological development of the paper is to extend the methods of Chen, Yi and Cook (Stat Med, 2010) to the case of a non-homogeneous Markov model using the time transformation model of Hubbard et al (Biometrics, 2008) rather than the piecewise constant intensities used in Chen, Yi and Cook. The authors claim that the time transformation model is more appealing than piecewise constant intensities because it requires fewer parameters. However, this parsimony is at the cost of flexibility, as the time transformation model assumes the same temporal trend for all intensities.

The assumption of non-informative examination times is an ever present spectre for multi-state models from panel data. Chen et al's method provides some methods when a complete set of planned examination times is known and it is simply the case that some examination times are missed, meaning the problem can be dealt within the Rubin framework of MAR/MNAR. A more general situation would be where the multi-state process and the process that generates the examination times are dependent. Here the only option seems to be to jointly model the two processes explicitly. A starting model might be one where the intensities of the counting process generating the examination times and the multi-state model are linked through a joint frailty, e.g. something analogous to models for joint modelling of longitudinal and (informative) drop-out (survival) processes.

Tuesday, 5 April 2011

Progression of liver cirrhosis to HCC: an application of hidden Markov model.

Nicola Bartolomeo, Paolo Trerotoli and Gabriella Serio have a new paper in BMC Medical Research Methodology. This applies a three state hidden Markov model to data on the progression of liver cirrhosis to Hepatocellular carcinoma. A time homogeneous continuous time progressive model is fitted with death as the absorbing state. Covariate effects are included via a proportional intensities model.
Schoenfeld residuals, which are appropriate for right censored data, are applied here as a test of proportionality. It isn't made clear precisely how this is done here. If time of death is known exactly then a Schoenfeld type residual could be defined for the times of death replacing the standard formulation


with


where If the times of death are interval censored then this approach is inappropriate.

On a more trivial level the matrix of misclassification probabilities is missing a 1 in the third row corresponding to the absorbing state.